Building a Lead Enrichment Pipeline With Web Scraping APIs
Live-web scraping replaces expensive static databases with fresh, cost-effective lead data.
Most teams that want better leads ask the wrong question. They ask "which database should we buy," when the real question is "how should the pipeline be built." Static databases charge for coverage they can't actually guarantee: a single provider typically matches only a majority of records, and B2B contact data decays at about 22 percent a year, so even a list bought yesterday starts going stale today. A live-web pipeline built around a scraping API flips that arrangement on its head. Freshness becomes a built-in property of the system rather than a feature you pay extra for, because every run pulls from the live web instead of querying a snapshot someone took months ago. The money involved isn't trivial, either. Commercial databases run annual licenses in the thousands to tens of thousands of dollars, while a custom pipeline can process hundreds of leads for a small fraction of that cost, which makes this a strategic call rather than a line item to argue about at budget time. None of that savings shows up automatically: it depends on the pipeline being built right. That means getting four stages in the correct order and wired together correctly. That four-stage architecture, Source, Enrich, Score, Route, is what the rest of this piece builds, piece by piece.
What a complete pipeline must produce
Before writing a line of code, it helps to know what "done" looks like for a single lead record. A record counts as enrichment-complete only when it covers five categories: firmographic data (industry, revenue, headcount, funding stage), technographic data (CRM, cloud provider, analytics stack), demographic data (role, seniority, function), behavioral and intent signals (hiring activity, recent funding, product expansion), and contact-level data (a verified work email and a direct phone number). Each of these categories does a different job once the record reaches a sales team. Firmographic and technographic fields feed ICP scoring and decide which accounts get prioritized first. Behavioral signals decide timing, and job postings are some of the strongest timing signals sitting out in the open on the public web: a company hiring a Head of Security is a decent fit for security tools, a company hiring Data Engineers needs data infrastructure, and a company hiring Account Executives has a sales budget that's growing. That's not a minor detail buried in a scraper's output.
This shapes how the pipeline gets designed, not just what it collects. Mapping desired output fields to sources before writing any code is the first architectural decision, because it determines which URLs to hit, in what order, and what extraction schema to define at each step. Skip that step and the schema gets invented halfway through a build, usually right after something breaks. Get it right at the start and every later decision, which sources to hit, what format to pull them in, how to score the result, has a target to aim at. The five-field framework is the spec the entire pipeline gets built to satisfy, not a checklist to glance at once.
The four pipeline stages and the logic connecting them
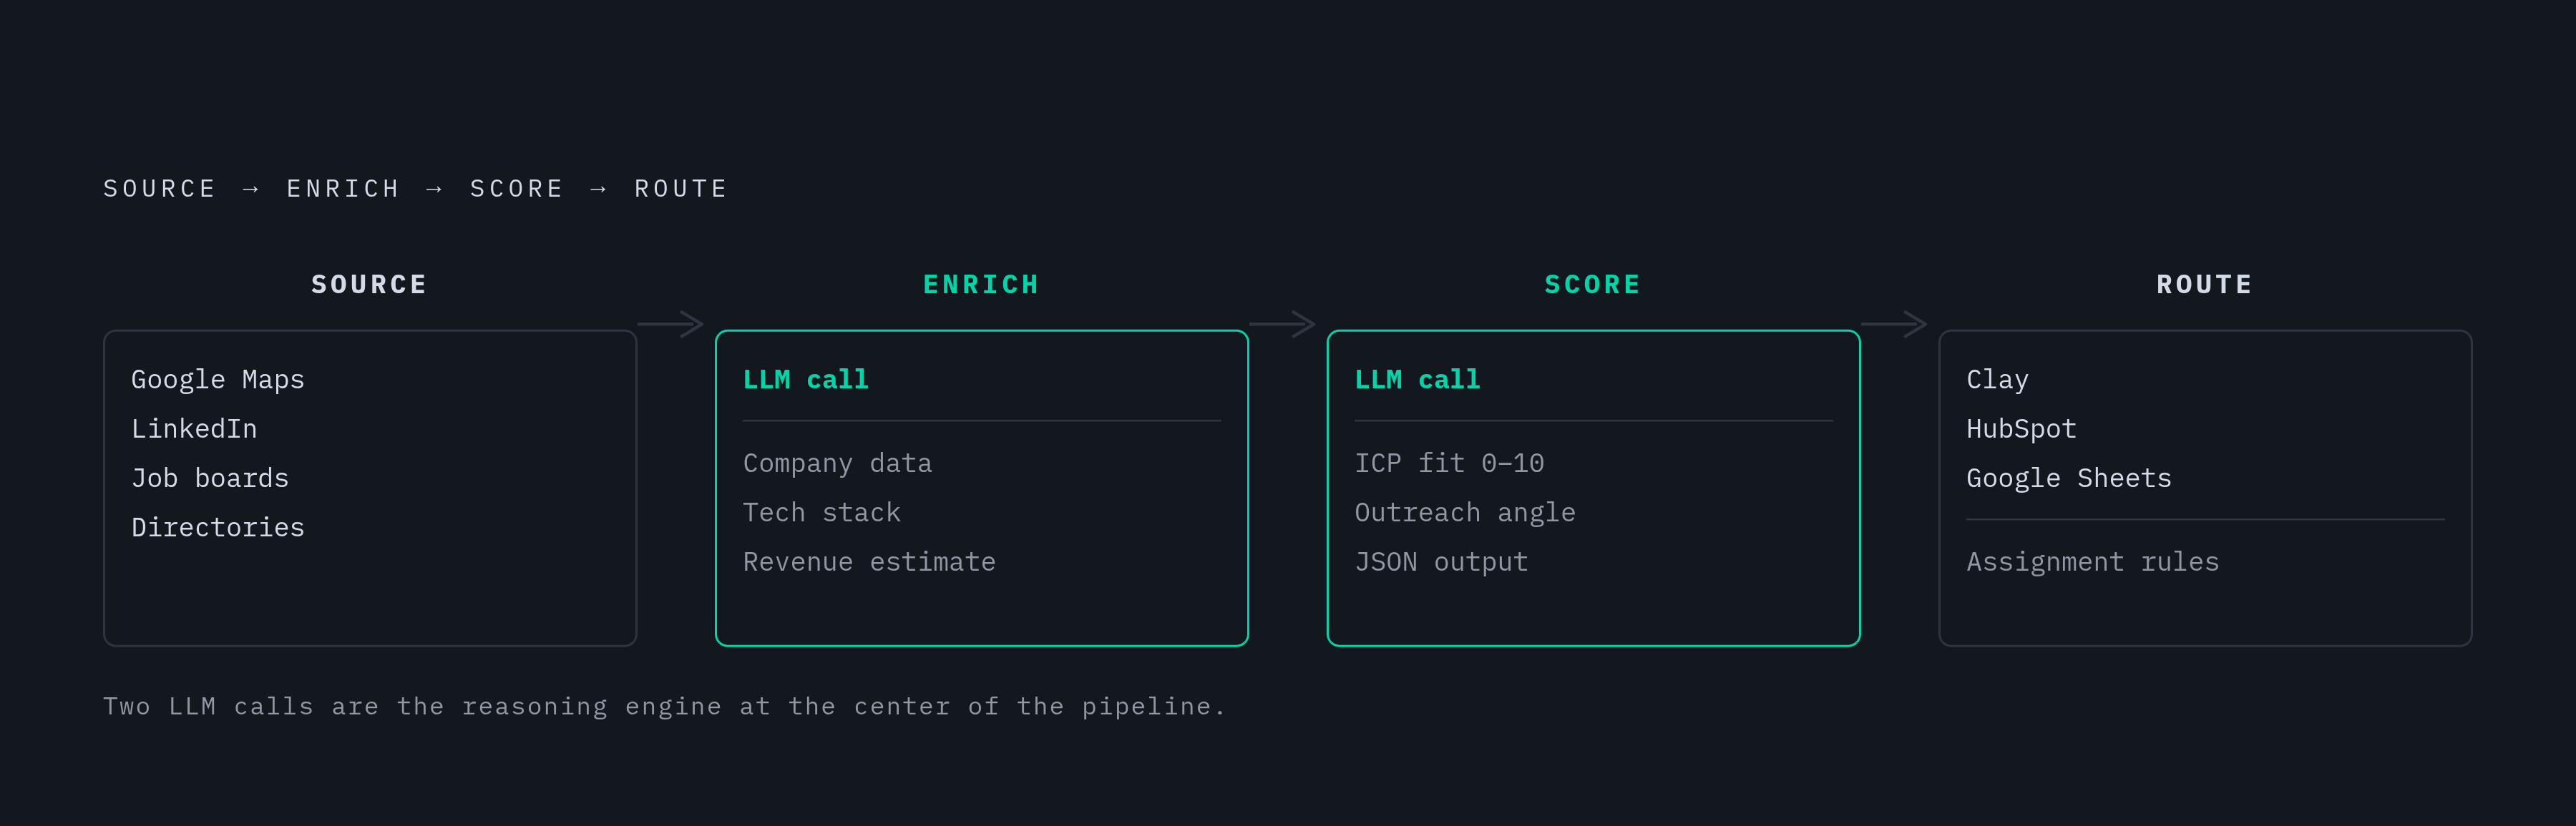
A properly built lead enrichment pipeline runs four stages, always in the same order: Source, Enrich, Score, Route. The flow looks something like this:
[ SOURCE ] -> [ ENRICH ] -> [ SCORE ] -> [ ROUTE ]
 scrapers LLM call LLM call CRM/sheet
 (Maps, (company (ICP fit, (Clay,
 LinkedIn, data, tech outreach HubSpot,
 job boards, stack, angle, JSON Sheets)
 directories) revenue est.) output)
Source is where scrapers pull raw lead data off public pages: Google Maps for local business records, LinkedIn company pages for headcount and industry, job boards for hiring signals, directories for contact formats. Enrich is where an LLM call takes that raw material and turns it into structured company intelligence, a description, a tech stack, a revenue estimate, pulled from the company website and other public sources through a scraping API. Score is a second LLM call that rates the enriched record against a defined ICP and writes a personalized outreach angle, handing both back as one JSON object. Route pushes that scored record into a CRM or a sheet, Clay, HubSpot, or Google Sheets, with assignment rules applied so it lands with the right person.
An orchestrator is what makes the pipeline run on its own. An orchestrator sits beneath all four stages, and tools like n8n use a node-based visual builder to schedule runs, retry failures, branch when a provider comes up empty, and send alerts when something needs attention. That orchestration layer is what turns the pipeline into something repeatable instead of a script someone runs once and forgets. Each stage has to hand off a clean, typed output that the next stage can use without extra cleanup work. That is why format turns into a structural question later in this piece, not a cosmetic one.
Sourcing: which public surfaces to hit and in what order
Picking sources isn't a matter of taste. The right order starts with whatever is cheapest and most reliable, saving the expensive or rate-limited sources for the gaps the cheap ones leave behind. That means starting with the company's own website, since a domain input yields a description, the primary product, the target customer, a location, and often a contact email, making it the cheapest scrape and the one most likely to succeed without JS rendering. From there, job postings on LinkedIn or Indeed turn up hiring signals: role titles and job descriptions reveal tech stack, growth stage, and rough budget signals without anyone needing to see a balance sheet. Crunchbase adds funding rounds and investor data on top of that, useful for narrowing a list down to companies that just raised money and have cash to spend. Tech stack detection tools such as BuiltWith or Wappalyzer identify what a company is already running, which is a strong ICP signal for anyone selling infrastructure or SaaS. Last in line is email pattern discovery through something like the Hunter.io API, which figures out a company's email format ahead of outreach but isn't a stand-in for an email address that's actually been verified.
Local business lead lists tend to lean hardest on Google Maps, and for good reason: the data is public, it shows up pre-packaged with phone numbers, addresses, website URLs, ratings, and business category, and there's no login wall in the way. That convenience comes with limits. Results cap out around 120 per query, and scraping the front end directly runs into Google's anti-bot defenses and its Terms of Service. The LinkedIn side of sourcing carries a similar weight. It's a real architectural constraint, not a footnote to mention in passing, and it shapes how proxies get configured and how many concurrent requests a pipeline can safely run against LinkedIn without getting flagged. Any pipeline design that treats LinkedIn like a normal open API is going to hit a wall fairly fast.
The scraping API as the load-bearing layer of the pipeline
The scraping API decides whether the whole pipeline produces data a sales team can use, or quietly falls apart once it's running at any real scale, rather than acting as a convenience layer sitting on top of plain HTTP requests. Three specific failure modes occur when raw HTTP requests are left to fend for themselves, and a managed scraping API is built to absorb all three.
The first is IP blocking and fingerprinting. Production targets spot and block naive request patterns fast, so residential proxy rotation and browser fingerprint randomization aren't nice extras, they're the baseline cost of staying connected to LinkedIn, job boards, and the larger directories over time. A managed API can turn on headless browser rendering only for the pages that actually need it, instead of paying that processing cost on every plain-HTML page it touches. The third is extraction itself. Instead of handing back raw HTML for the application to pick apart later, a capable scraping API hands back clean Markdown or typed JSON directly, which happens to be exactly the format the LLM enrichment stage needs to do its job.
Building this in-house is possible, but the math rarely works out. In-house scraping infrastructure comes with a large upfront development cost and takes months to reach something stable enough to run in production, while managed APIs get a pipeline running in days to weeks for a fraction of that spend. The economics only tilt toward building it yourself at volumes high enough that most teams never actually reach them.
Output format: why clean Markdown and typed JSON are architectural requirements, not style choices
Whatever comes out of the scraping stage becomes the floor for every stage built on top of it. Bad extraction produces bad chunks, bad embeddings, and LLM outputs that sound confident while being wrong, because the model is reasoning over text that's malformed or missing pieces to begin with. Feeding raw HTML straight into an LLM makes this worse in both directions: it costs more to process and gives the model a messier starting point than it needs, so a pipeline should never hand over raw HTML when a structured option is sitting right there.
Two output formats cover two different jobs inside the pipeline, and using the wrong one forces an unnecessary conversion step or routes data through an LLM that a direct field lookup could have handled. Markdown earns its keep whenever the job is "give the model the readable content of this page." Headings, lists, and tables stay intact, while navigation menus, cookie banners, and footers get stripped out, and Markdown breaks into chunks in a predictable way that works well for embeddings. JSON earns its keep whenever specific typed fields are what's needed, a price, a job title, a list of open roles, a funding round, since the application can query those fields directly instead of routing them through an LLM first. Most working enrichment pipelines use both at once: Markdown to chunk and embed for retrieval-based steps, JSON to fill in the structured CRM record the pipeline is ultimately built to produce. Research testing LLM-based extraction pipelines has turned up high F1 scores on text and table extraction from unstructured sources, and the practical upshot is simple: feed the model clean input, and LLM extraction holds up well enough to trust running at production scale. The design rule for the Enrich stage is Markdown for reading, JSON for recording, and nothing passed downstream in a format the next stage wasn't built to read.
Enrichment and scoring: wiring the LLM into the pipeline as a reasoning step
The Enrich stage is a reasoning step: the model gets clean Markdown or structured JSON from the scraping API and is asked to extract facts, classify them, and synthesize something new out of them, rather than just pulling a value out of a table that already has the answer sitting in it. A single API call to a model like Claude can return a JSON object carrying an ICP fit score from 0 to 10 along with the reasoning behind it, plus a two-sentence email opening built around specific details pulled from the scrape, like a recent funding round or a job posting for a Head of Security.
A sketch of the pattern looks roughly like this:
def score_and_pitch(enriched_record: dict, icp_spec: dict) -> dict:
 prompt = build_prompt(enriched_record, icp_spec)
 response = claude_api_call(prompt)
 return {
 "score": response["score"], # 0-10
 "reasoning": response["reasoning"],
 "email_opening": response["opening"],
 "pain_point": response["pain_point"]
 }
The input is an enriched record, company description, employee count, tech stack, job postings, funding data. The output is one JSON object with a score, the reasoning behind it, a personalized opening line, and a likely pain point. None of this works well if the ICP gets redefined by hand every time the pipeline runs. Company size, industry, revenue range, geography, tech stack signals, buying signals, and disqualifiers should get written once into a reusable prompt, then reused every time a new record gets scored against it. The scoring step also decides when a record needs a human to look at it. Records missing a LinkedIn URL or a reliable domain fail automated matching at a meaningful rate, so a confidence threshold should route anything uncertain into a review queue instead of letting it overwrite good CRM data.
Handling enrichment failures with a conditional fallback loop
Sources miss matches constantly. That's not an edge case worth engineering around later; it's the normal state of working with public data, and a pipeline that handles it well runs conditional fallback logic instead of fixed fallback logic.
A static waterfall checks source one, then source two, then source three, in the same order every time, and when all three come up empty, the field just stays blank. A conditional loop behaves differently: when a provider returns no match, the system queries the next appropriate source instead, another API, a web search, a direct scrape, rather than giving up and leaving a gap in the record. When two sources return conflicting values for the same field, the system resolves that conflict using recency and reliability rather than defaulting to whichever source happened to run first. Anything still uncertain after that gets routed to a human review queue instead of getting written straight into the CRM and treated as fact.
This plays out in practice: Clay's own users report spending one to two weeks just configuring the priority rules for their first waterfall, sorting out which source wins when two providers disagree, which gives a sense of how much manual effort the static approach demands before it even starts running. Sim's agent-based enrichment model shows the conditional version in practice: the agent applies conditional logic at each step, normalizes whatever comes back from different providers into one CRM schema, deduplicates before writing anything, and sends low-confidence matches to a human for approval, a pattern any developer can build with an orchestration layer that supports branching logic. In n8n, that pattern is implemented as a branch node placed after each provider call. Confidence below the threshold routes to the next source in line. All sources exhausted flags the record for review. Only a confident match moves the record forward to scoring.