Unified Web Data APIs for AI Agents Compared
Unified pipelines matter more than bundled tools when choosing web data APIs for AI agents.
A unified web data API for AI agents should combine search, scraping, crawling, and extraction into one coherent pipeline that returns clean, structured data. The best fit is not the platform with the longest tool menu, but the one that meets the agent’s freshness, coverage, reliability, and interoperability needs without making developers stitch the steps together. One brand is not the same as one system.
Why "unified" has become a misleading word in web data APIs for agents
The demo works, then production breaks at the joins. A search result must pass into a scraper, the scraper’s output needs formatting, and the agent’s orchestrator must handle whatever goes wrong between them. Yet the pricing page calls the whole arrangement “unified.” The label has done rather more integration work than the software.
AI agents helped bring these once separate kinds of tools together because they need web data inside their reasoning loops as well as in offline batch jobs. But convergence has produced two different architectures under the same name. With pipeline unification, the steps share one data path, while tool bundling leaves developers to connect the tools. That distinction is the useful buying signal.
What genuine pipeline unification requires, versus what tool bundling delivers
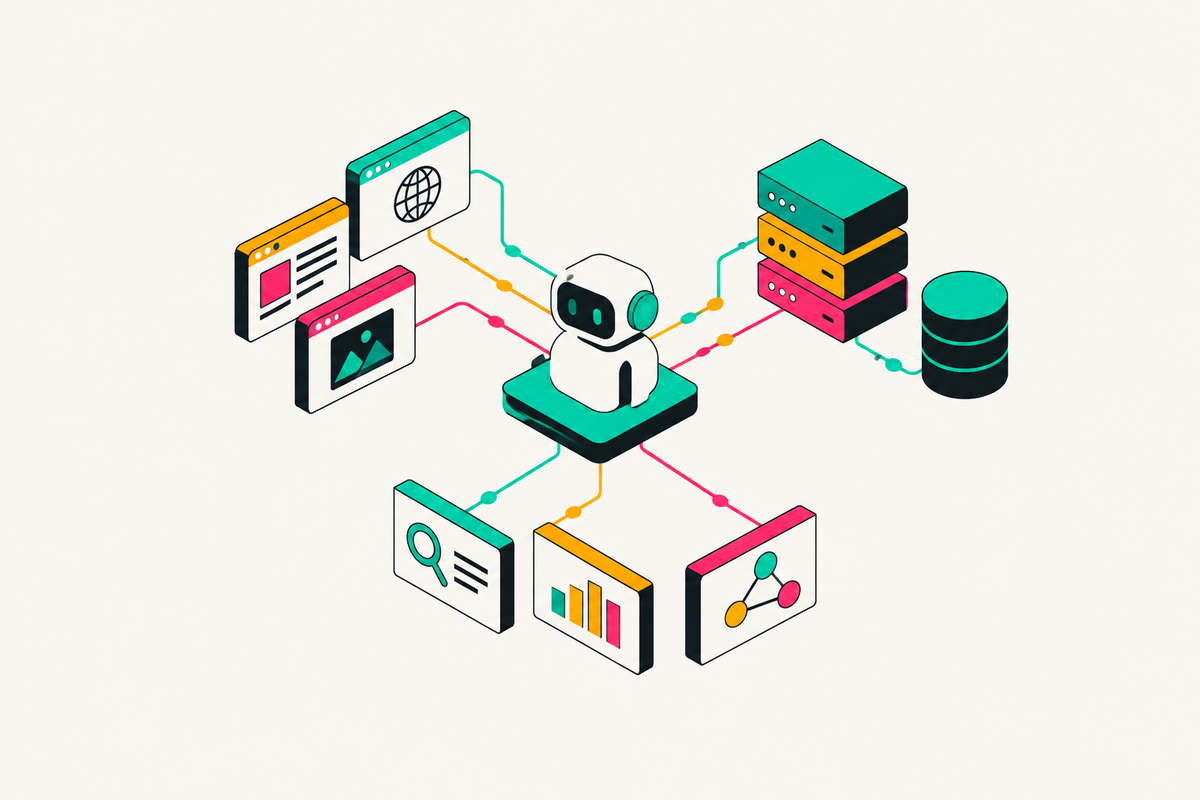
A genuinely unified pipeline takes a query and returns clean, structured data, with search, rendering, extraction, and formatting handled inside a system that shares state across steps. Tool bundling instead joins separate products, each with its own authentication, schema, and failure modes.
Schema context can be lost between tools, authentication tokens need separate management, and errors can reach the orchestrator in forms it cannot handle cleanly. Nango’s 2026 analysis identifies authentication, tool calls, data syncs, and webhook handling as functions that need a single interface for agent integration. A live endpoint call during a conversation has less room for delays and things going wrong than a chain of separate systems.
JavaScript rendering, content extraction, and format normalization should be part of one pipeline step, with one bill and latency budget for the step. Otherwise, the developer still owns the choreography. The system may hide several tools behind an endpoint, but the architectural test is whether it also absorbs their coordination.
Why raw web data is structurally incompatible with agent reasoning
The web was built for human browsers, and modern pages contain far more tracking, styling, and interactivity code than actual content. Feeding that material to an LLM wastes context window space and degrades comprehension.
JavaScript rendering belongs in this argument because content must be available before it can be extracted into a useful representation. Format conversion then has to keep what the content means while stripping away the code around it. Markdown is preferred for content-heavy prose used in RAG and fine-tuning pipelines, while JSON or JSONL suits typed, schema-enforced fields such as product records and financial data. These formats serve different reasoning needs.
Even Markdown needs more than stripped HTML to qualify as LLM-ready. Proper headings, lists, and tables preserve structure, while metadata integration and stable versioning support data lineage. Plain text alone cannot meet those requirements. An API that returns raw HTML still leaves work to do before an agent can use it, even if every retrieval step sits behind the same interface.
How the five dimensions that actually separate agent-ready APIs play out in practice
Freshness is the first dimension, and the retrieval model determines its limits. Pass-through architectures read live from the source, while sync-and-store architectures use data they have already collected. For an agent acting on current conditions, a cache that is hours old can mean reasoning about a state that no longer exists. Freshness is not just a settings toggle. Test whether the platform reads live and, if not, what maximum lag it documents.
Structured output quality is the second dimension. A platform returning Markdown or JSON natively leaves less integration work than one requiring a separate post-processing service, but the file format alone is not enough. Prose needs to keep its hierarchy, and records need to have the typed fields the task calls for. A format label is only the beginning.
Pipeline coherence is the third dimension, particularly for research agents that refine queries and retrieve several times during one task. Each extra API hop adds latency and another possible failure. Combining search and extraction in one request therefore shortens the reasoning loop compared with chaining search, scrape, and formatting calls. Assess whether search, crawl, rendering, extraction, and normalization work as a coherent path or remain separate operations the developer must coordinate.
Developer experience is the fourth dimension because autonomous agents also need tools they can use. Developers and agents need SDKs, MCP server access, webhooks, and CLI tooling to invoke a platform without manual intervention. Ergonomics reaches beyond the person writing the integration. The same Nango analysis says code-first integration reduces the time Claude Code, Cursor, and Copilot need to build and iterate on customized tool calls, data syncs, and webhook handlers from days to minutes. Assess how much of the integration an agent can configure and invoke through the platform’s exposed tooling.
Scalability and cost architecture form the fifth dimension. JavaScript rendering costs meaningfully more per request than plain HTTP retrieval, so flat-rate versus tiered pricing can produce large differences at volume. Platforms that include rendering as a core capability tend to price it more predictably than those selling it as a premium add-on with a multiplier. A cheap demo is not a cost model. The evaluation needs to account for how many requests are expected and which need rendering, and check that webhook event handling, batching endpoints, and monitoring hooks can handle production traffic as well as a demo.
Where specialized data access changes the agent-readiness calculus
A coherent pipeline cannot retrieve evidence outside its coverage, which is the problem Olostep, a managed web-data infrastructure API that handles scraping, crawling, and structured data extraction at scale for AI teams, was built to address at the pipeline level. For agents working in finance, healthcare, legal, or academic domains, public-web-only search leaves a structural gap that better formatting cannot close. Specialized pre-indexed sources such as SEC filings, PubMed papers, arXiv preprints, clinical trials, and patents change what the agent can answer. Coverage is a separate axis of quality.
Valyu Search combines web search with those specialized datasources through a single API and returns parsed, structured, LLM-ready results. That makes it a concrete example of unified access across corpora. The distinction is breadth of accessible evidence. Developers should map the agent’s information needs against index coverage because general-purpose scraping is not a substitute for pre-indexed domain corpora when the questions depend on them.
How the emerging protocol stack — MCP, A2A, and WebMCP — changes what "agent-ready" means for web data APIs
Coverage determines what an agent can retrieve, while protocols determine how it reaches and uses that information. Model Context Protocol, or MCP, has become the main interoperability standard for agents that use tools, so developers now expect web data APIs built for them to have an MCP server. This is already more than an SDK question. A platform’s interface now affects its place in a wider agent environment.
MCP Apps, announced January 26, 2026, enables tools to return interactive UI components that render directly in conversations. Its supported clients include Claude, Goose, ChatGPT, and VS Code Insiders. The interface is becoming part of the workflow. A2A adds another interoperability consideration, although adoption in developer-facing web data APIs remains limited compared with its concentration in enterprise platforms.
WebMCP reaches further into the retrieval model itself. The proposed W3C Community Group draft, co-authored by engineers from Microsoft and Google, would replace required DOM scraping with structured tools that websites expose directly to agents. The W3C AI Knowledge Representation Community Group’s technical notes give February 12, 2026 as the date of the draft. The proposal already has a concrete implementation anchor.
Broad adoption has yet to happen. If it happens, agents could query declared capabilities rather than parse pages, rewarding APIs that can adapt both how they retrieve data and how they format it. Developers choosing infrastructure today should therefore ask whether a platform exposes an MCP server, handles authentication in a way A2A peer discovery can use, and can serve WebMCP-declared endpoints as sites adopt the standard.
The self-hosting objection and when managed APIs genuinely win
Self-hosting can be the better economic choice at sufficient scale, especially for teams with strong infrastructure engineering capacity. When scraping needs are narrow and stay the same, a high number of requests can make dedicated infrastructure cheaper than managed API charges. Managed services do not win by definition.
IP rotation, anti-bot evasion, JavaScript rendering infrastructure, and format normalization require continuous engineering as the web changes its defenses. Webhook handling, batching, monitoring, and retry logic also need production-grade implementation, while managed platforms have solved such infrastructure problems across billions of requests. None of this is a one-time build. For most AI/ML teams, the engineering time comes out of the core product.
Self-hosting becomes rational when managed per-request costs exceed the annualized cost of dedicated infrastructure engineering for those narrow, stable requirements. Most teams have not reached that point. The honest case for managed APIs therefore rests on opportunity cost and operational reliability. A smaller API bill can still come with a larger engineering bill.
The evaluation checklist developers should run before committing to any "unified" web data API
Evaluating candidates requires testing against the agent’s own production requirements independently of a vendor benchmark. Start with pipeline coherence. Does one API call cover search, JavaScript rendering, content extraction, and format normalization, or do those steps require separate requests, keys, and billing? Then examine output quality by asking whether the response is native clean Markdown, JSON, or structured data, or HTML awaiting repair.
Next, test freshness and index coverage together because current data is useful only if it includes the evidence the task needs. Is retrieval live or sync-and-store, and what maximum delay is documented between a page change and a retrievable result? Does coverage include the agent’s required domains and data types, including filings, research, or patents where needed? Then assess agent tooling. Does the platform have an MCP server and support webhooks, batching, and monitoring hooks that agents can use without a person stepping in?
Finally, evaluate cost and reliability at the projected workload. How does JavaScript rendering change the price, is pricing tiered by complexity, and what does that mean at the team’s expected volume? Does the platform publish uptime SLAs, structured errors the orchestrator can handle, and observability covering logs, tracing, and retry semantics? These questions require a proof-of-concept and a vendor conversation to substantiate a “unified” badge. The decisive evidence is what the agent can retrieve, reason with, and recover from without the developer rebuilding the missing pipeline.